Korveniq AI
Evaluation before launch: how we test AI answers against business risks
The new evaluation loop combines expert criteria, automated checks and a log of disputed answers.
K
Korveniq EditorialKorveniq News editor
7 MIN READ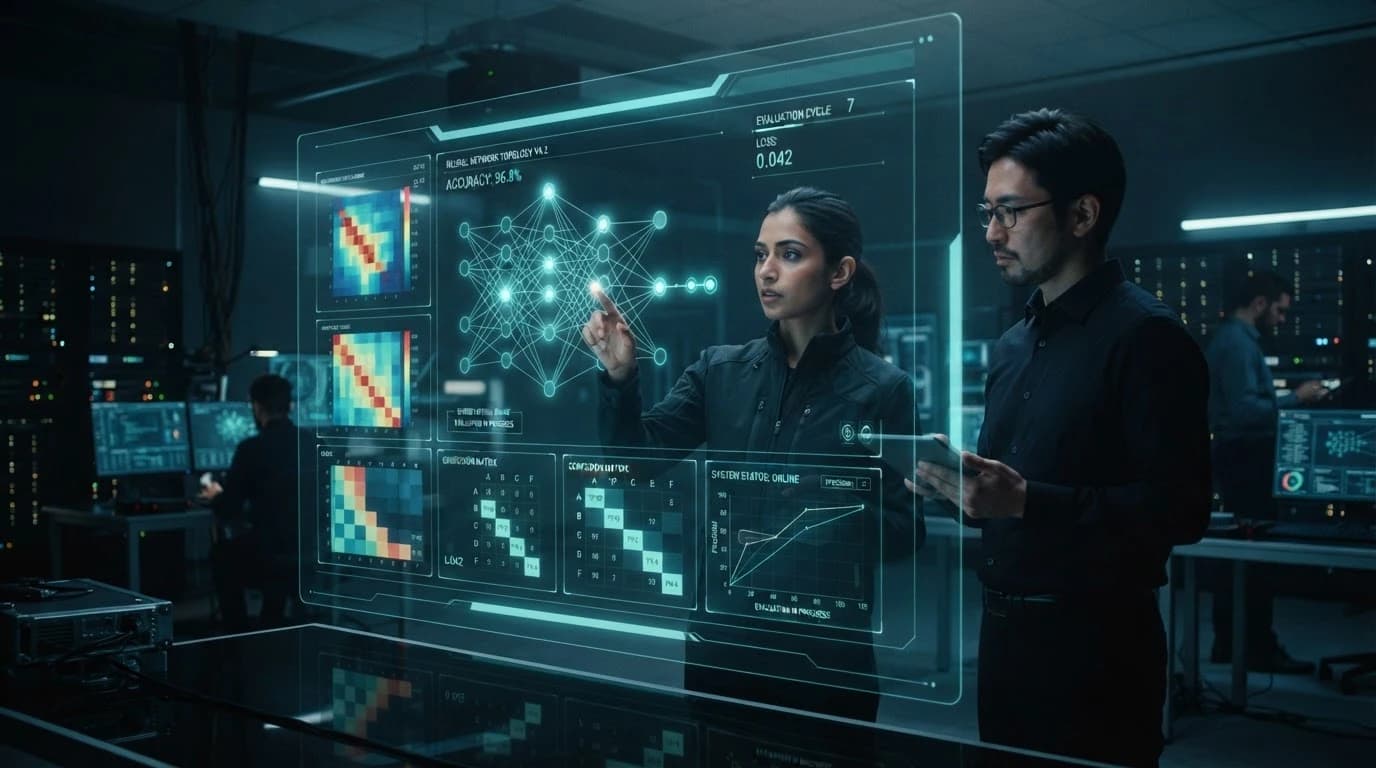
The evaluation loop checks AI answers before launch against the criteria that matter to the business.
KORVENIQ AI / 2026
An AI system's answer can be smooth and convincing yet wrong or risky for the business: an imprecise statement of terms, an unwarranted promise to a customer, disclosure of data that should not have appeared. Ordinary “correctness” tests do not catch such risks.
At Korveniq AI we built an evaluation loop that checks answers before launch. It combines expert criteria, automated checks and a log of disputed answers, and the assessment is built around the business risks of the specific scenario.
Starting from risks, not metrics
For each scenario we describe, together with the client, which errors are most costly: wrong price information, a breach of internal policy, an answer outside the system's competence. These risks become the basis of the check set.
This order guards against a system that shows good average scores but errs systematically exactly where the cost of error is highest.
WHAT THE EVALUATION LOOP CONSISTS OF
01Risk mapA description of the most costly errors for a specific scenario.
02Expert criteriaWhat counts as a correct, complete and acceptable answer.
03Automated checksRepeatable scoring of answers on a set of test queries.
04LogDisputed answers, expert decisions and accumulated examples.
“Good evaluation does not ask ‘how close is this answer to a correct one’, but ‘how could this answer harm the business’.”
Expert criteria and automated checks
Domain experts formulate the criteria: what counts as a correct, complete and acceptable answer. These criteria become verifiable rules and examples.
Automated checks run over a large set of test queries and score answers against the criteria. The assessment repeats after every change of model, prompt or knowledge base and does not depend on reviewing each answer by hand.
3parts of the loop: criteria, automated checks, log
1risk map per scenario
∞re-runs after every change
A log of disputed answers
Not every answer can be judged automatically. Disputed cases go into a log where an expert decides and records why an answer was accepted or rejected.
The log gradually becomes part of the check set: a disputed case resolved once no longer has to be settled again, and the system will not return to the same error unnoticed.
Disputed answers are reviewed by an expert and feed back into the check set.
How it fits into launch
Evaluation results are part of the launch-readiness criteria: a scenario goes live only after the risks agreed in advance have been checked and residual limitations described.
After launch the same loop is used for regular checks to notice quality degradation after updates. The Korveniq AI team can help build such a process for your scenario.
Check AI answers before launch
In 45 minutes we will discuss your scenario's risks and choose evaluation criteria that reflect their cost.
MORE FROM KORVENIQ
Keep reading
Korveniq Technologies, Korveniq AI and the CEO column — in one editorial stream.