Korveniq AI
Korveniq AI publishes an open benchmark for Russian-language RAG systems
12,000 test queries help compare retrieval quality, answer completeness and robustness to noise.
K
Korveniq EditorialKorveniq News editor
4 MIN READ
An open benchmark lets teams compare RAG systems on the same Russian-language data.
KORVENIQ AI / 2026
RAG systems are increasingly the foundation of corporate assistants: they answer employee and customer questions based on internal documents. But when a team chooses between several approaches, there is little to compare them on — most public tests are built on English-language data.
Korveniq AI is publishing an open benchmark for Russian-language RAG systems. It helps check not only the quality of the final answer, but also how reliably a system finds the right fragments and relies on them.
Why a separate benchmark in Russian
Russian brings its own difficulties to retrieval and generation: rich morphology, free word order, abbreviations and mixed languages in business documents. Approaches that work well in English are not guaranteed to behave the same on Russian text.
The benchmark contains 12,000 test queries close to real ones: questions about policies, contracts, technical documentation and support knowledge bases.
WHAT THE BENCHMARK CHECKS
01RetrievalWhether the system finds relevant fragments in Russian-language documents.
02GroundingWhether the answer is built on retrieved data rather than model guesses.
03CorrectnessWhether the final answer matches the source documents.
04AbstentionWhether the system admits when information is insufficient.
“RAG quality cannot be judged by one number: you need to see where retrieval breaks and where generation does.”
What is measured and how
Evaluation is split into stages. Retrieval is checked separately — does the system find the right fragments — and generation separately: is the answer correct, does it rely on the retrieved context, and does the system admit when data is insufficient.
This split shows exactly where quality is lost. If an answer is wrong because of poor retrieval, improving the generation model is pointless, and vice versa.
12,000test queries
2separate stages: retrieval and generation
100%open data and methodology
Open data and reproducibility
Task sets, evaluation criteria and run instructions are published openly. Any team can run its own solution and get comparable results, rather than relying on vendor claims.
We plan to develop the benchmark with the community: accepting new tasks, refining criteria and versioning releases so results from different periods stay comparable.
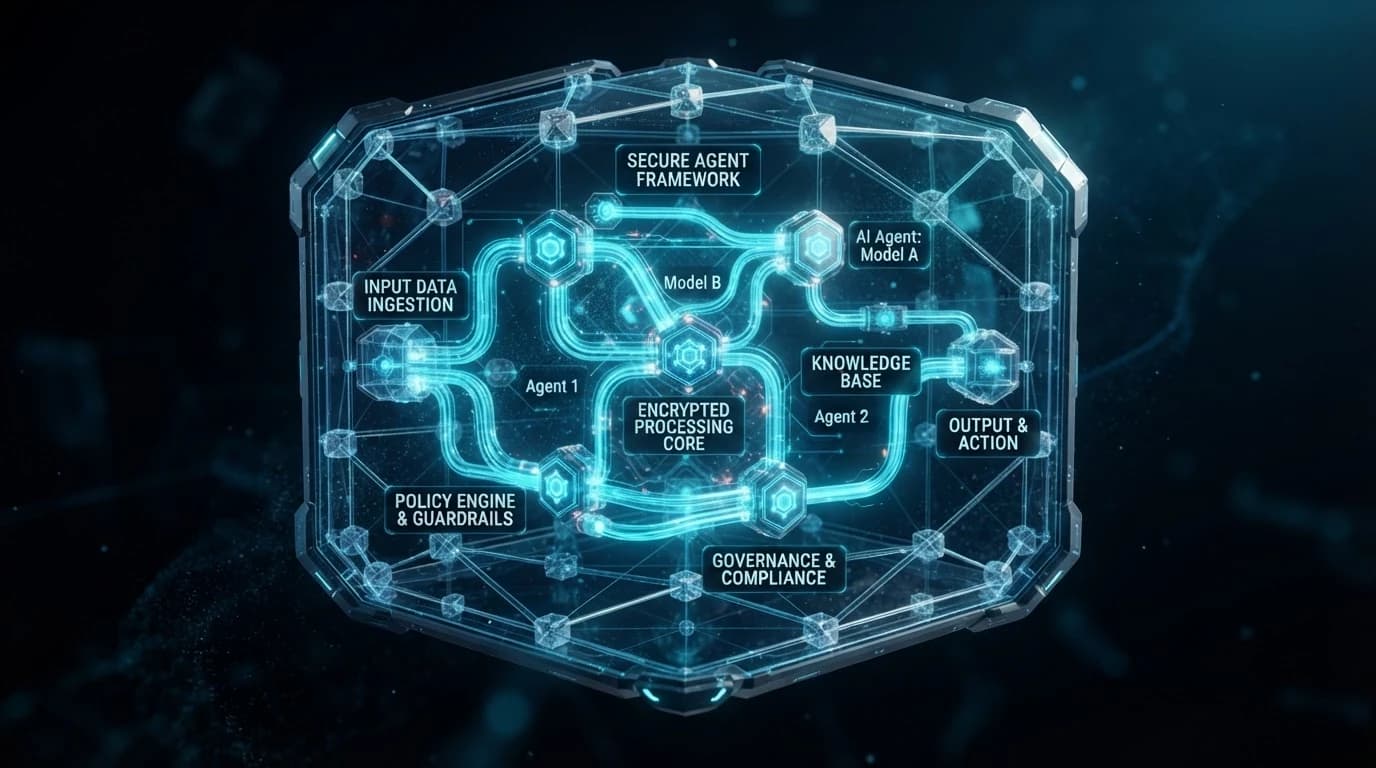
Separate evaluation of retrieval and generation shows which part of the system to improve.
How to use the results
The benchmark is useful when choosing an architecture and for regular checks of a running system: after changing the model, index or document set you can quickly see whether things got worse.
Teams adopting RAG in their processes can reach out to Korveniq AI: we will help select metrics for your data and build quality checks into your development process.
Check RAG quality on your data
In 45 minutes we will discuss your scenario and choose metrics that reflect the system's real value.
MORE FROM KORVENIQ
Keep reading
Korveniq Technologies, Korveniq AI and the CEO column — in one editorial stream.